How variation became something science could study
Why do repeated measurements differ? How can a small experiment support a larger conclusion? What separates a real effect from an accidental pattern?
In The Lady Tasting Tea: How Statistics Revolutionized Science in the Twentieth Century, David Salsburg tells the history of these questions through the people who developed modern statistics. His central argument is that statistics changed the objects and methods of science. Researchers learned to study distributions of possible outcomes, rather than search only for exact laws governing individual observations.
This is an intellectual history told through working problems and personal disputes. Its central achievement is to show why methods that now appear in textbooks were once difficult inventions.
The tea test: turn disagreement into a fair experiment
The opening story concerns a woman who says she can taste whether milk or tea entered a cup first. Ronald Fisher proposes testing her claim. The productive move is to specify what evidence would distinguish an ability from successful guessing.
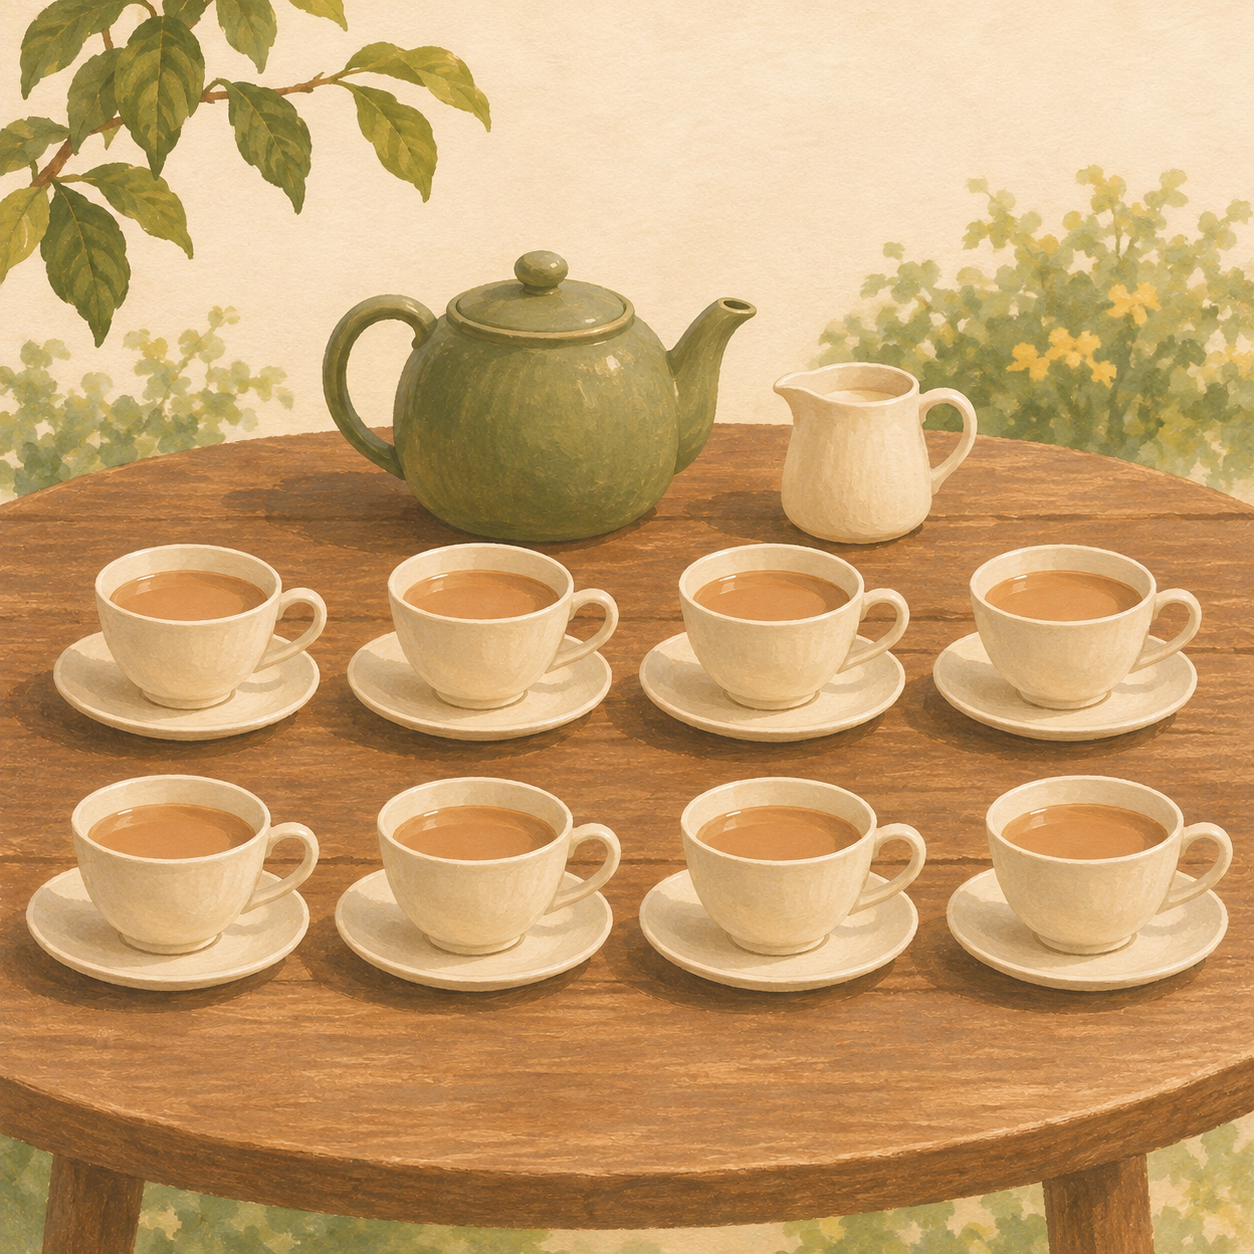
In Fisher’s published design, the taster receives eight cups in random order. Four were prepared each way. She knows these totals and must divide the cups into the two groups.
There are 70 ways to choose four cups from eight. Only one choice identifies the four milk-first cups correctly. Under the no-ability assumption and the randomized design, a perfect classification therefore has a probability of 1 in 70, about 1.4 percent.
This probability describes success under a specified assumption. It does not give the probability that the woman lacks the ability. It also does not establish that she could repeat the performance under every condition.
Random order matters because the arrangement must not supply clues. The rules matter because investigators should decide how to interpret outcomes before seeing them. A careful design makes the calculation meaningful.
The hero illustration is a conceptual tea-test still life, rather than a reconstruction of the historical gathering.
Distributions describe more than an average
A distribution describes which outcomes are common, which are rare, and how widely they vary. Two processes can have the same average yet behave very differently.
Consider an illustrative example. Two filling machines may deliver the same average amount. One produces nearly identical fills. The other alternates between underfilling and overfilling. The average hides a difference that matters to customers and the manufacturer.
Salsburg traces the work of Karl Pearson and others who tried to describe variation with mathematical families of distributions. A parameter is a number that describes a feature of a model, such as its center or spread. Estimating these numbers lets researchers move from a sample of observations to a description of a wider process.
The choice of distribution remains an assumption. The familiar bell-shaped normal distribution is useful in many settings, but it cannot serve as a universal picture of data. An elegant model still needs to fit the problem.
Gosset: small samples need an honest account of uncertainty
William Sealy Gosset worked at Guinness and published statistical research under the name Student. His practical setting matters. A brewer cannot always obtain the enormous samples that make mathematical approximations convenient. The Dictionary of Irish Biography documents his work connecting brewing problems with statistical theory.
With a small sample, the average is uncertain. The sample’s estimate of the underlying variation is uncertain too. Treating that second estimate as exact can make conclusions look more secure than they are.
Student’s t methods account for this additional uncertainty when their assumptions hold. The t distribution has heavier tails than the normal distribution: it allows more room for unusually large departures. As the relevant degrees of freedom increase, it approaches the normal curve. NIST’s technical reference explains this relationship.
The lesson extends beyond brewing. A useful method must reflect what the investigator actually knows. Small samples can support inference, but they do not justify unlimited confidence or remove the need to examine assumptions.
Fisher: good analysis starts before collecting data
Salsburg’s publisher excerpt describes Fisher confronting agricultural records in which fertilizer changes and weather differences were tangled together. The difficulty was not simply a shortage of observations. The comparisons could not cleanly separate the effects.
This problem is confounding. If one fertilizer is used in a wet year and another in a dry year, the harvest difference cannot be assigned to fertilizer alone.
Experimental design addresses the problem in advance. Compare treatments under shared conditions. Repeat comparisons to assess variation. Use random assignment to support a fair comparison and a defensible account of chance differences.
For an illustrative garden trial, put both fertilizers into the same season’s experiment. Group comparable plots, then randomly assign treatments within those groups. This reduces the risk that soil differences explain the result. Randomization does not guarantee identical groups; it provides a known assignment process on which inference can rest.
More observations cannot automatically repair a comparison that never separated the competing explanations.
Statistical evidence has competing meanings
One of the book’s most useful themes is disagreement within statistics. Fisher, Jerzy Neyman, and Egon Pearson did not offer interchangeable answers to the question of how evidence should guide belief or action.
Fisher’s significance testing asks how incompatible the observations are with a proposed explanation. Neyman and Pearson developed rules for choosing between hypotheses while controlling error rates over repeated use. Their framework distinguishes a false alarm from failing to detect an effect. Power is the probability that a test detects a specified alternative when it holds.
A test can therefore have a low false-alarm rate yet miss effects frequently. Calling a result insignificant does not establish that no meaningful effect exists. A historical analysis of significance testing explains why combining these traditions without understanding their aims creates confusion.
Confidence intervals address uncertainty in an estimate. A 95 percent confidence procedure produces intervals that contain the target value in about 95 percent of repeated samples, under its assumptions. The percentage describes the procedure’s long-run coverage. It does not assign a 95 percent probability to the fixed target lying in this particular observed interval. NIST explains this distinction.
Bayesian inference takes another route. It combines a prior distribution with a model for the evidence to obtain an updated distribution. The book introduces this competing tradition, but its historical account should not be treated as a complete guide to choosing between approaches.
Factories, medicine, and computers widen the field
The industrial story includes W. Edwards Deming and statistical quality control. The key question becomes whether a process shows ordinary background variation or evidence of a specific change.
Imagine a packing line whose output fluctuates slightly each day. Adjusting the machine after every small change may introduce further instability. A control chart places measurements in time order and helps identify patterns that warrant investigation. A point within the limits does not settle the issue: a sustained shift can also matter. NIST’s control-chart guide makes this clear.
The book’s smoking discussion exposes another difficulty: causal inference when people cannot ethically be assigned to harmful exposures. Fisher challenged the smoking–cancer interpretation. The episode shows that expertise in statistical theory does not guarantee sound judgment about a particular body of evidence. Doll and Hill’s long-term study examined patterns, including changes after quitting, that competing explanations needed to address.
Later developments use computing to investigate uncertainty. In the ordinary bootstrap, an analyst repeatedly samples with replacement from the observed data and recalculates a statistic. The resulting variation can approximate its sampling uncertainty. Bradley Efron’s original paper develops the method through estimation problems. Reusing a biased sample does not make it representative; computation expands analysis without creating missing evidence.
What readers can apply, and where the history has limits
My practical reading of Salsburg’s history is to ask four questions whenever a numerical claim appears:
- What process produced the observations, and who or what was left out?
- Does the comparison separate the proposed cause from other explanations?
- Which assumptions make the uncertainty calculation valid?
- Is the effect large enough to matter, beyond passing a statistical threshold?
The last question also appears in later guidance. The American Statistical Association’s 2016 statement stresses that a p-value does not measure effect size, practical importance, or the probability that a hypothesis is true. This is later context, not a claim that Salsburg wrote about that statement.
The book’s accessible biographies also impose limits. Verbal accounts can explain a method’s purpose without equipping readers to use it correctly. In his contemporary review in Nature, David Colquhoun praises the personal stories but disputes parts of Salsburg’s account of science’s shift away from determinism. Variation caused by measurement error differs from variation inherent in a physical process. Statistics helps study both; it does not make them identical.
Read the book as a history of changing scientific questions and methods. Its most durable insight is that reliable knowledge depends on how observations are produced, which comparisons they permit, and how honestly uncertainty is expressed.
Sources
- Macmillan: book details and Salsburg’s opening chapter; Google Books: publication record and contents.
- Ronald Fisher: original tea-test exposition; Dictionary of Irish Biography: William Sealy Gosset.
- NIST: t distribution, confidence intervals, and control charts.
- Historical analysis of significance testing; American Statistical Association: 2016 statement on p-values.
- Doll and Hill: mortality and smoking, 1964; Efron: original bootstrap paper, 1979.
- David Colquhoun: contemporary Nature review and critical perspective.
